Profiling
A column called status tells the model little. One whose profile says it holds P, S and C, never empty, tells it how to filter. Profiling reads a sample of each table and keeps, per column, what it found: distinct values, how many are missing, the range of numbers and the most frequent values. Qry then uses it in three places:
- Answers — the model sees each column's profile next to its name and type, so its first query filters on values that exist.
- Readiness for AI — profiles are how Qry finds the coded columns whose values a schema should explain, and a schema not profiled, or profiled long ago, shows it as a gap.
- The table page — the Profiling tab shows the same figures to anyone who can open the table.
A profile describes a sample, never the whole table: "sample rows" is how many rows Qry read.
Admin › Profiling
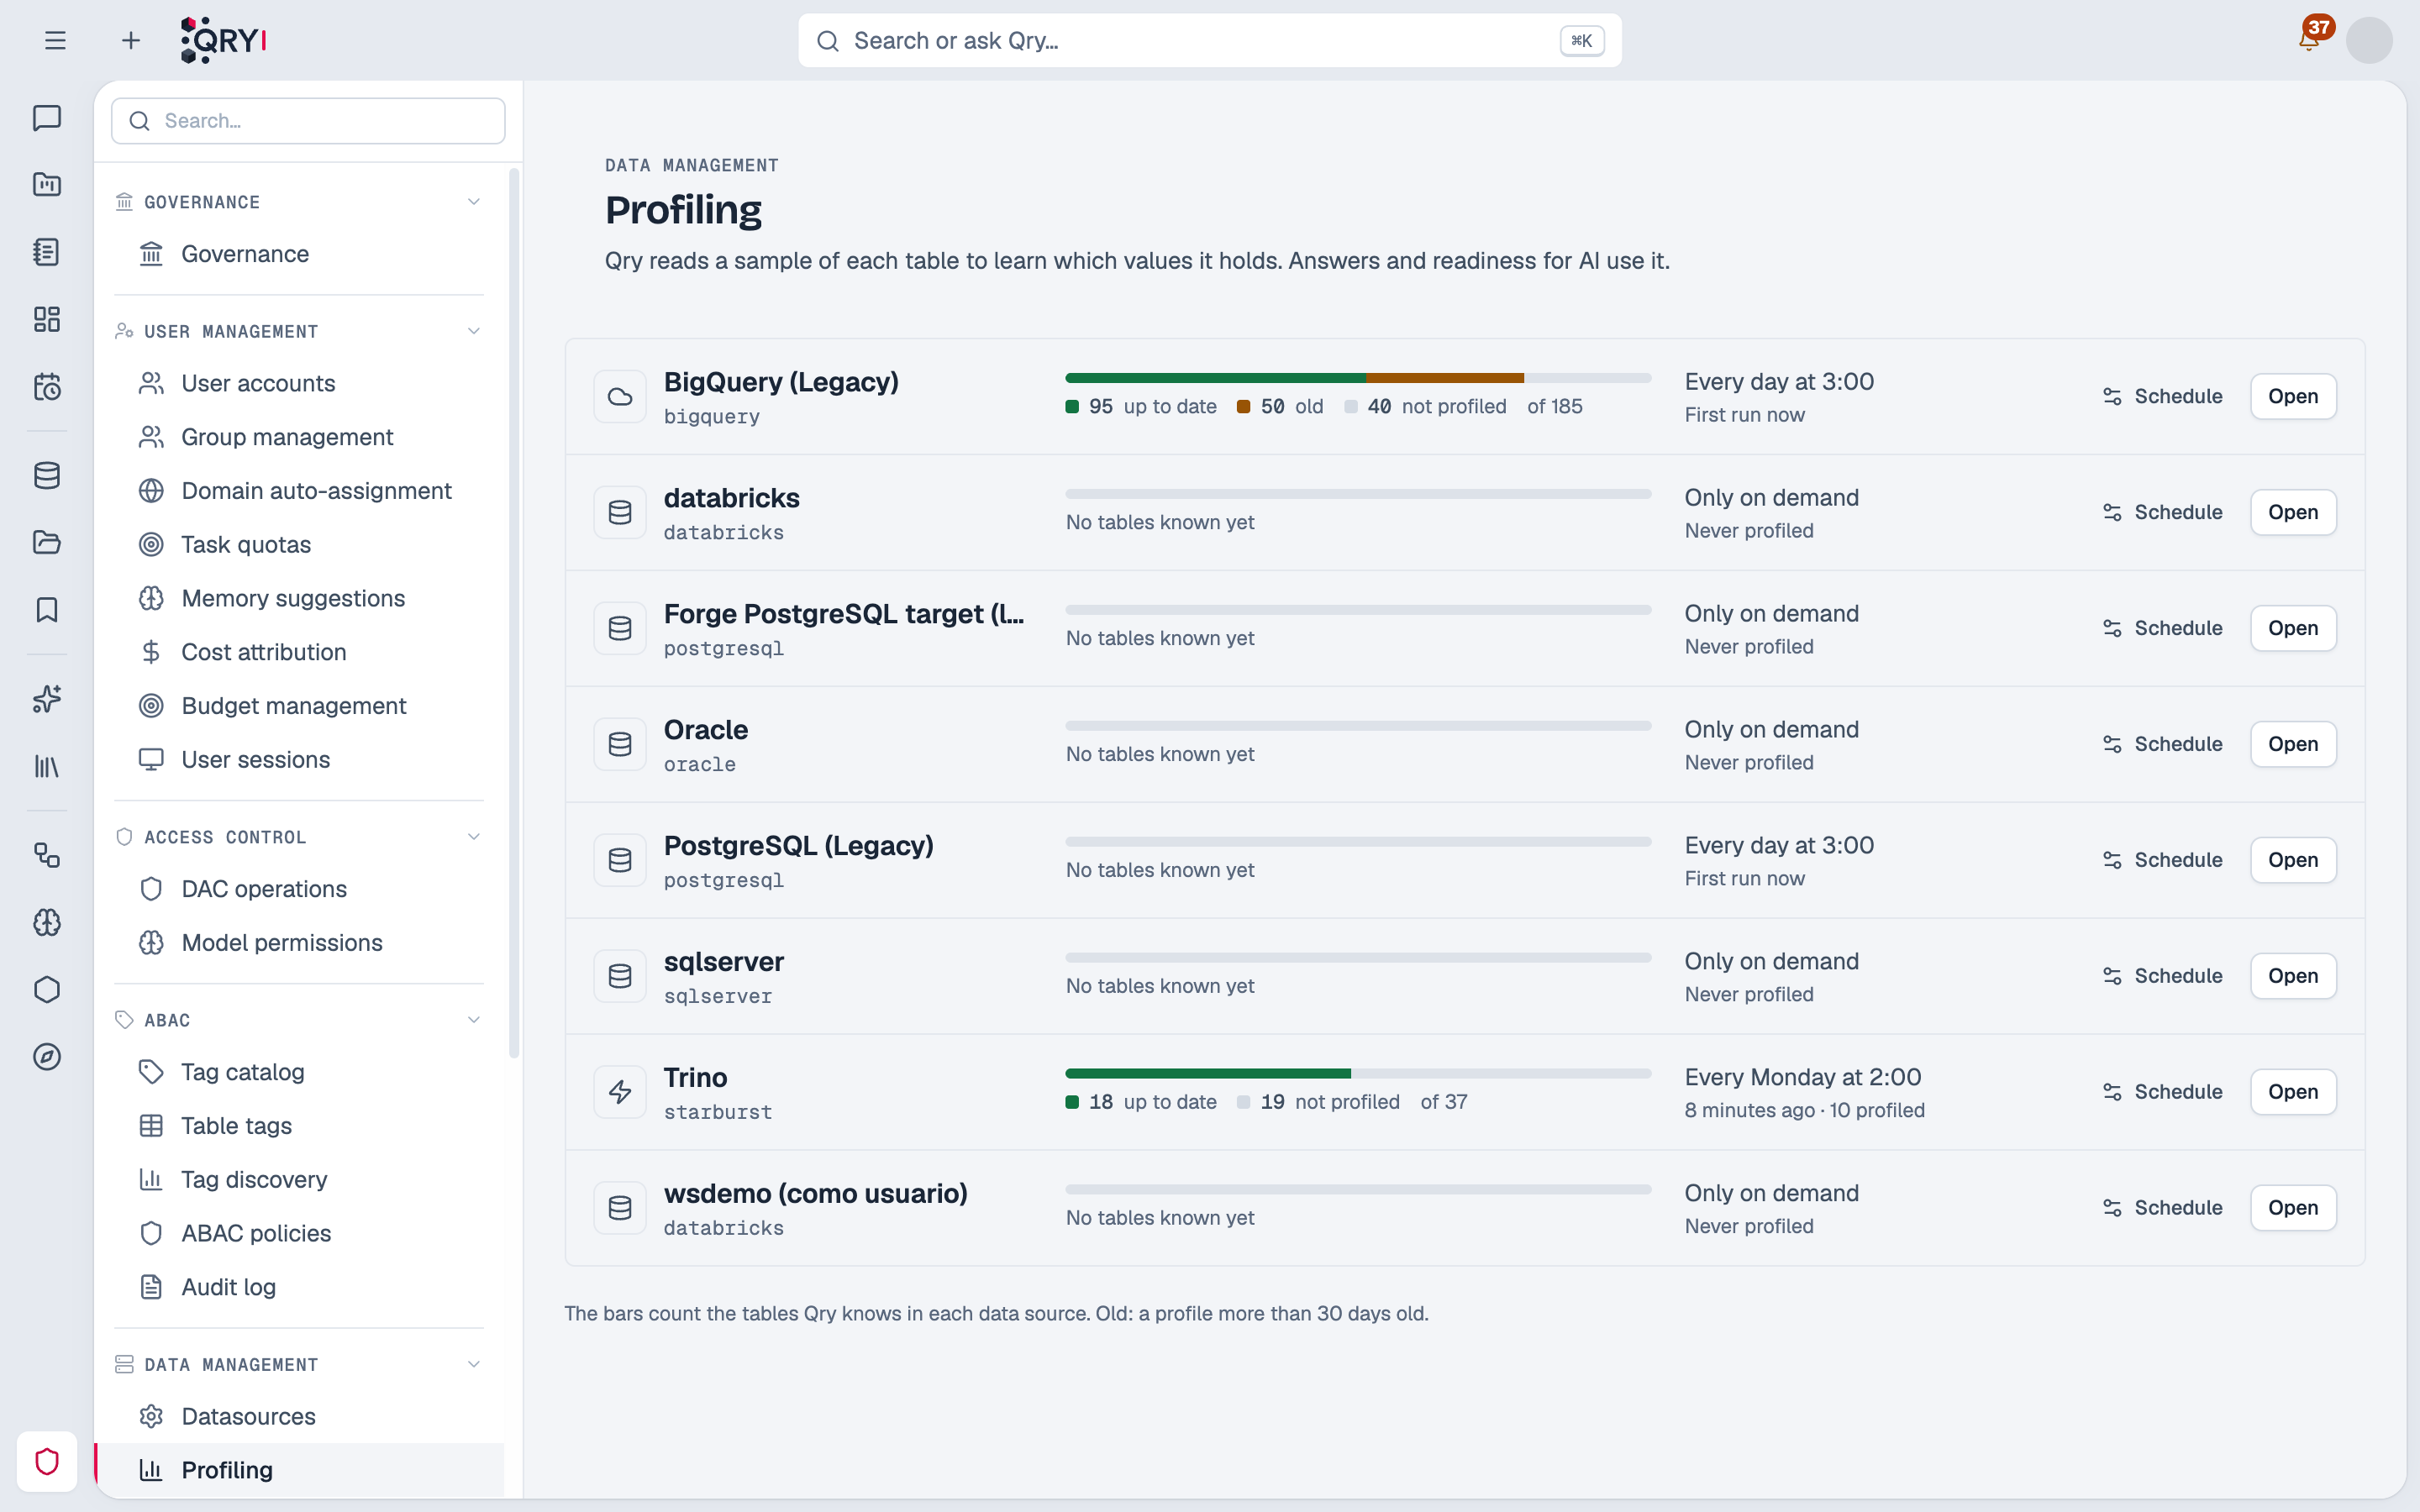
Admin › Data management › Profiling lists every data source with how much of it has a profile: up to date, old (more than 30 days), failing, or not profiled — counted over the tables Qry knows in each.
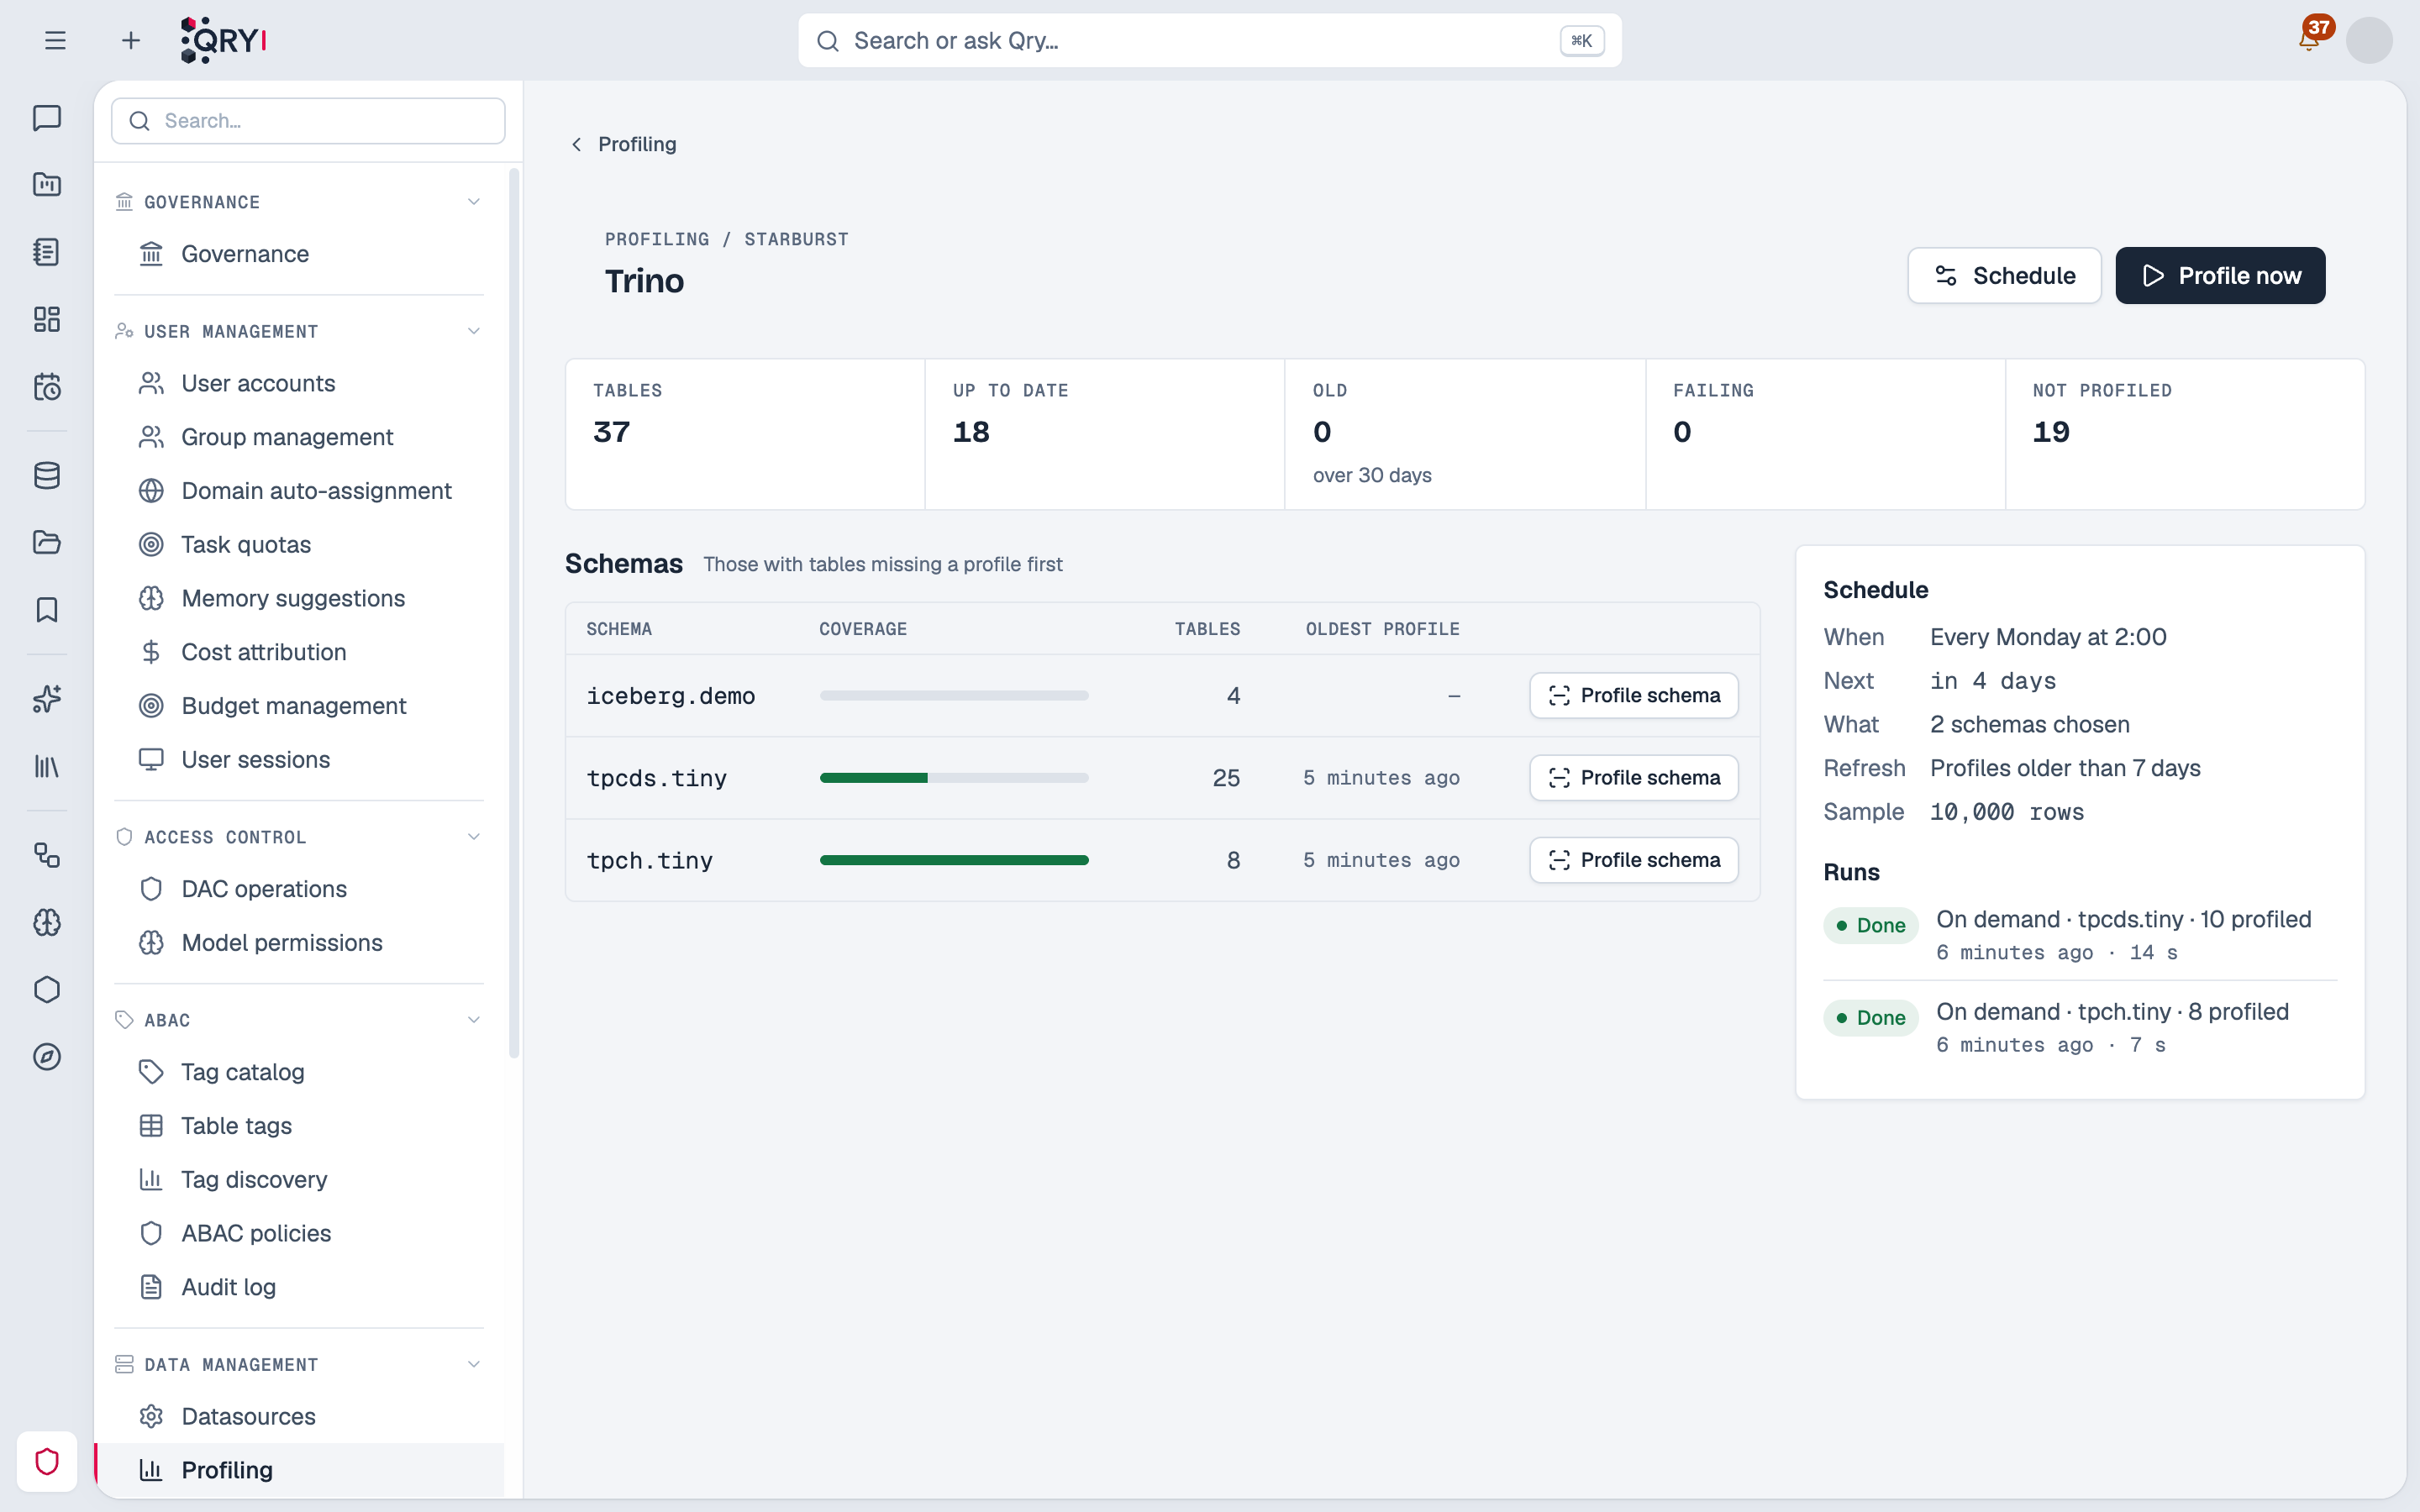
Opening a data source shows its schemas, those missing a profile first, with what each holds and a Profile schema button; next to them, the schedule and the last runs, each with what it came to.
Who sees this page: administrators, and the people who administer that data source. Everyone else asks for it (below).
Profiling where the gap is
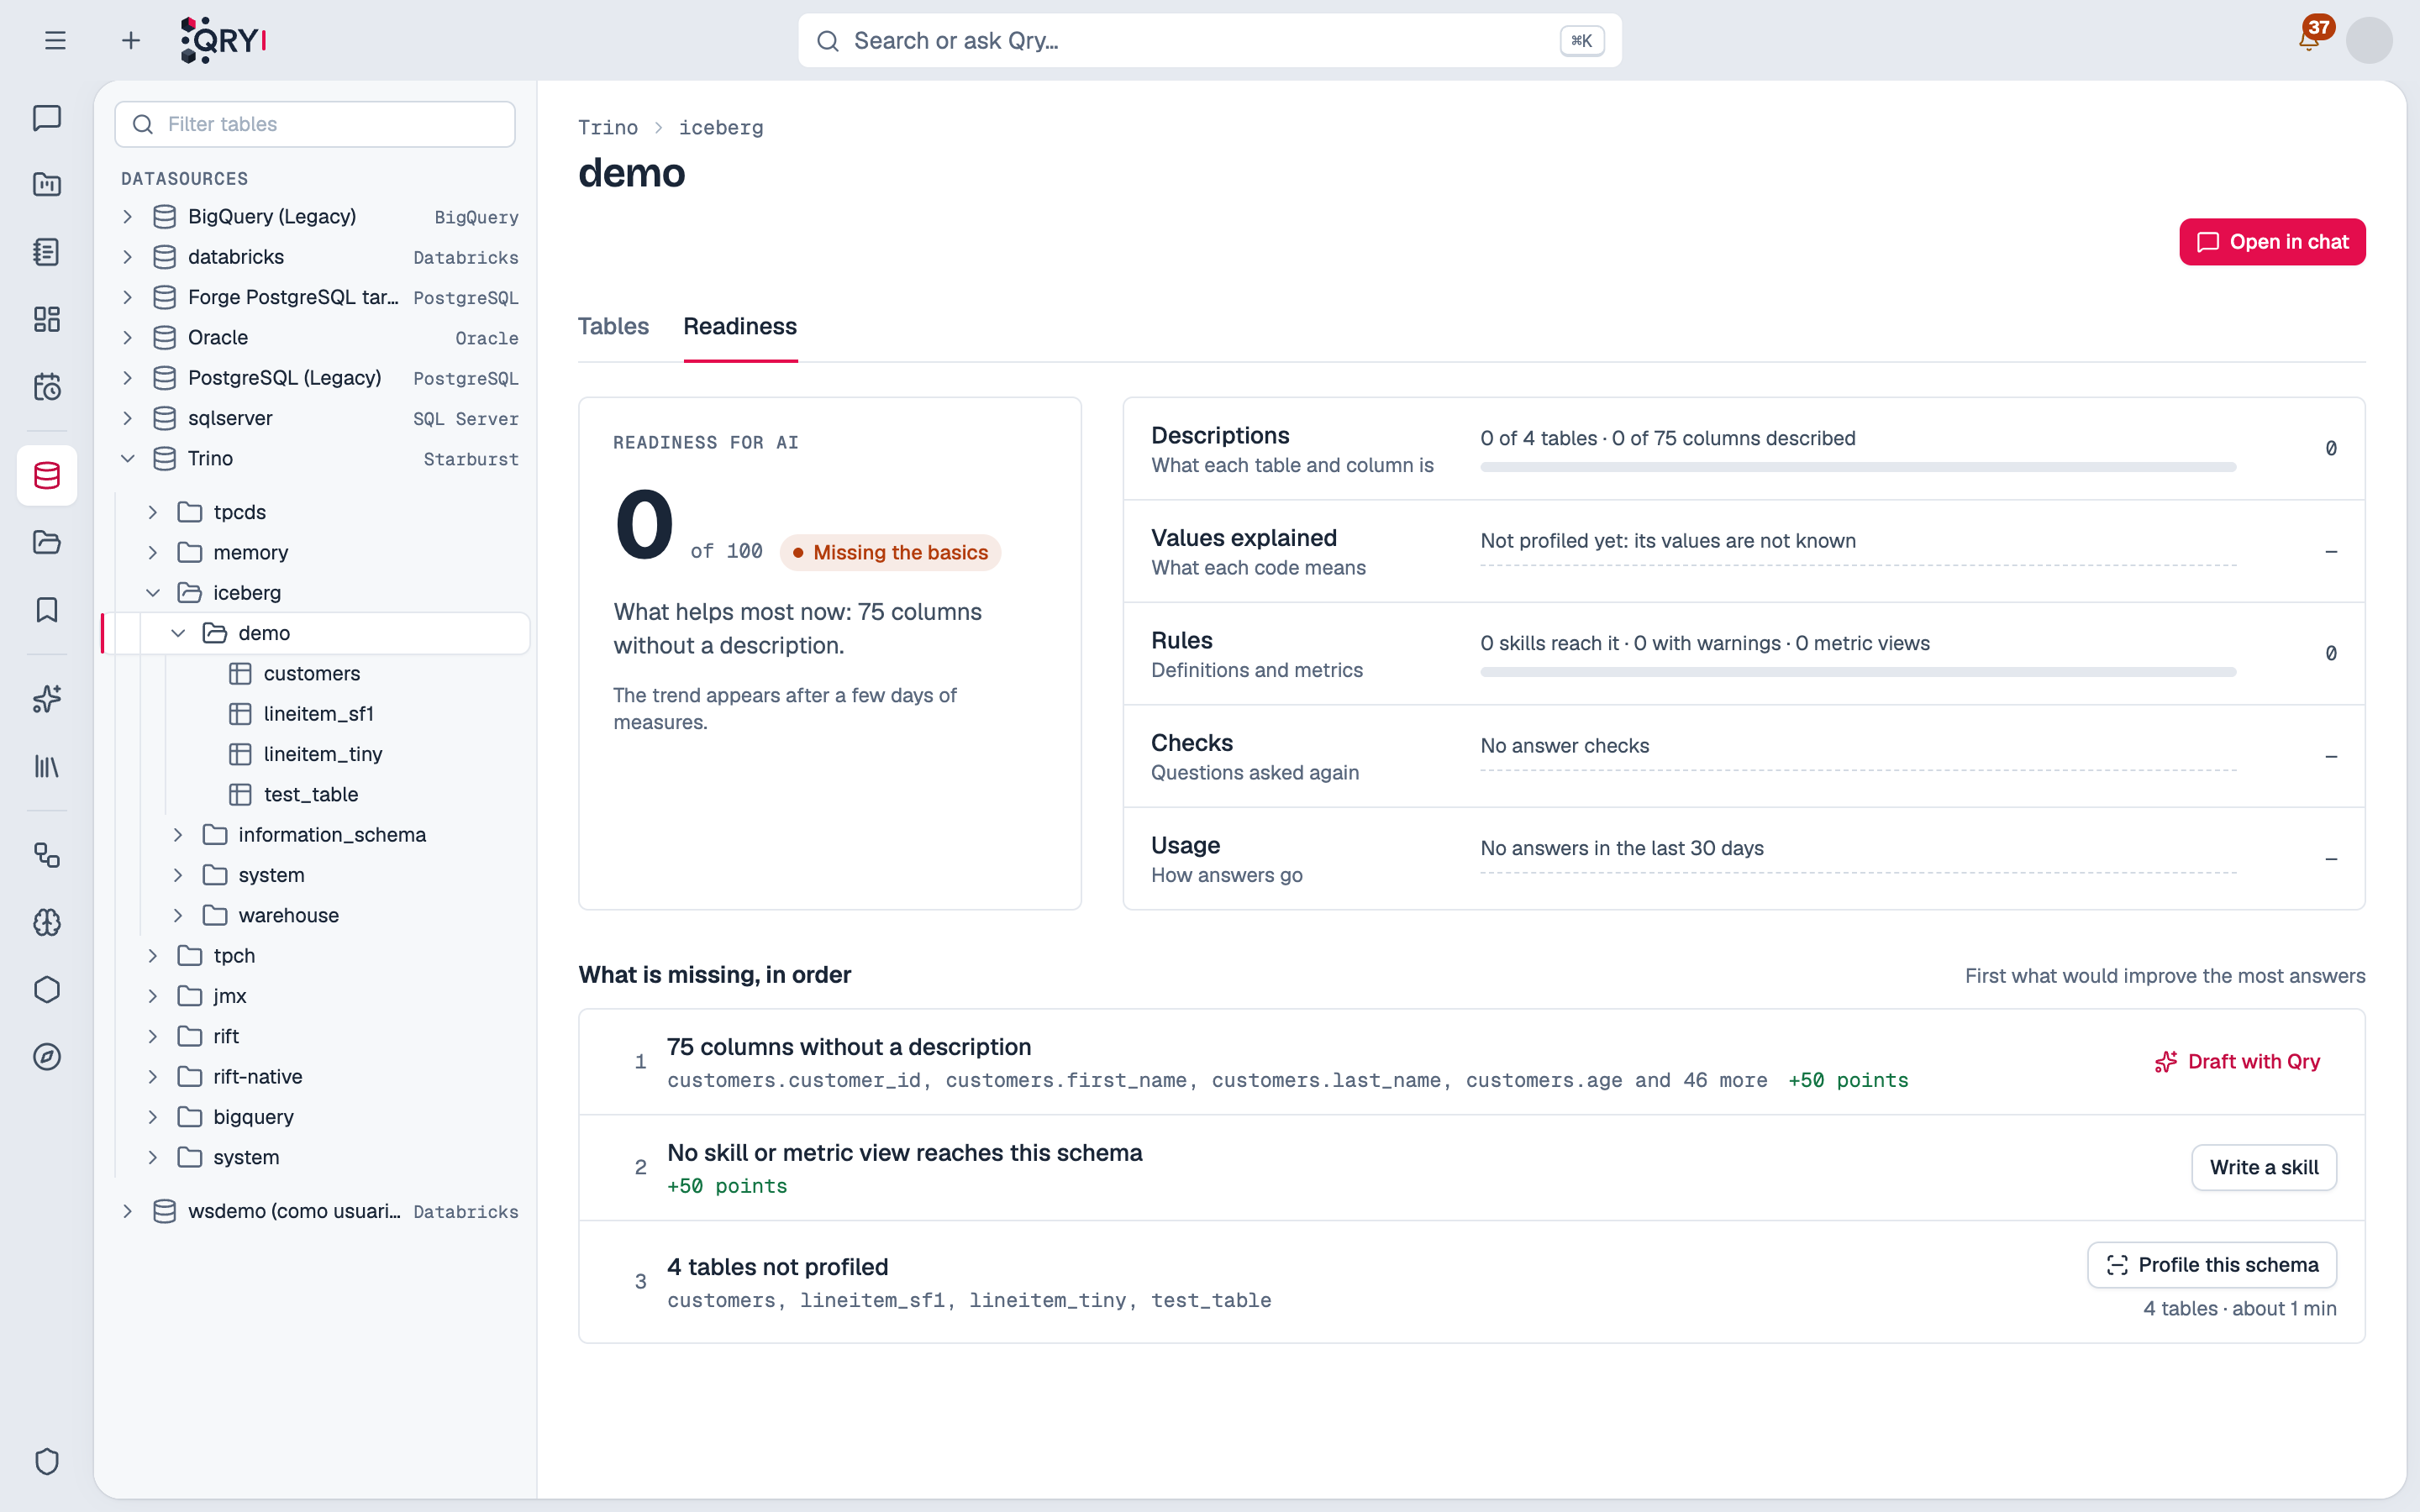
Nobody needs to come to the admin page for one schema. Where a schema's readiness says tables not profiled or profiles older than 30 days, the gap carries the action:
- an administrator of the data source sees Profile this schema, with how many tables and what it will cost, and follows the run in the row; when it ends, readiness measures the schema again;
- anyone else sees Ask for it to be profiled: the data source's administrators who can reach that schema get a notice under Approvals (at most one a day per schema), and nothing runs until one of them starts it.
A table page does the same for one table: Profile this table when it has no profile, Profile again when it has one.
Scheduling
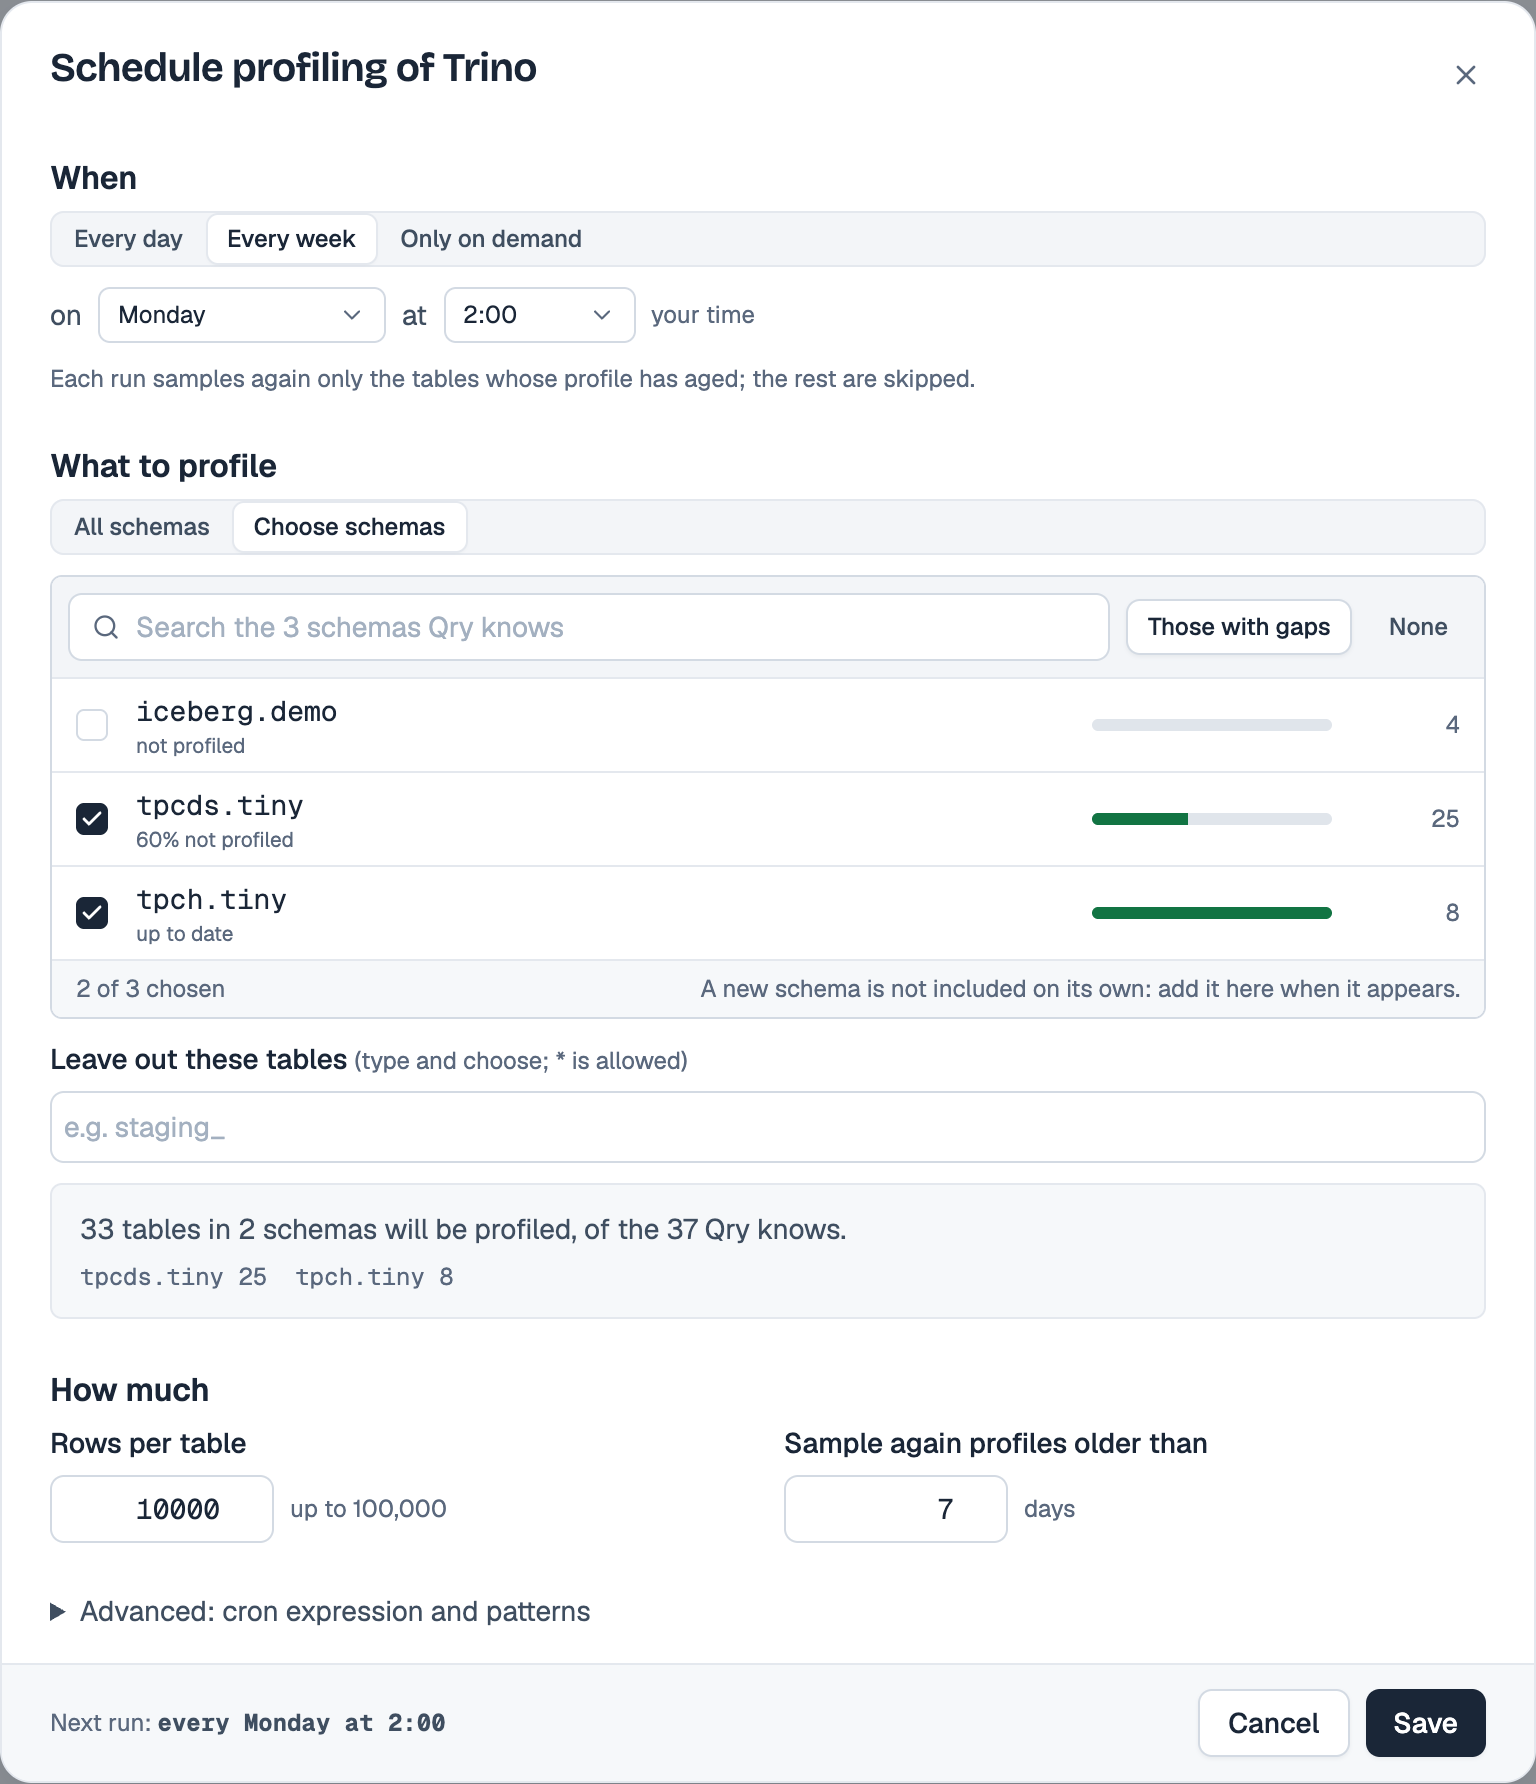
Schedule on a data source opens what runs on its own, in your own time zone:
- When — every day, every week, or only on demand. A scheduled run samples again only the tables whose profile is older than Sample again profiles older than (7 days by default); the rest are skipped, so a daily schedule does not read every table every day.
- What — all schemas (including those that appear later), or the ones you choose. A schema is shown with its catalog when the data source has more than one (
tpch.tinyandtpcds.tinyare two schemas). The preview counts, from what Qry already knows, how many tables a run would profile. - Leave out these tables — names or patterns (
staging_*), each saying how many tables it catches. - How much — rows per table (up to 100,000) and, on BigQuery, the most a view may cost (see below).
- Advanced — a cron expression (UTC) and schema patterns, for what the choices above do not express.
Without a schedule nothing is profiled on its own; schemas are still profiled on demand.
What a run does
Every profiling — scheduled, Profile now, a schema, a table — is a run: it records its scope, who started it, each table's outcome and why one failed. Runs go on the Celery dataflow queue; a scheduled one starts within the hour of its time.
- One table has at most 5 minutes; one that fails or runs out of time is recorded with its reason, and the others go on.
- A table that fails says so where it is read: the schema's readiness lists the tables that failed last time with the engine's message, and the table page shows it above the profile. Profiling it again does not help until the cause is fixed (a permission, a broken view).
- When a scheduled run has failures, the data source's administrators are notified. Whoever starts a run is told when it ends.
- A run whose worker disappears (a restart, a pod killed for memory) stops moving; after 20 minutes without progress it is closed as did not run, so it neither shows as running for hours nor blocks the next one.
- Tables no longer in a schema lose their profile when the schema is profiled again.
Cost on each engine
Profiling reads a sample, never the whole table:
| Engine | How it reads |
|---|---|
| BigQuery | Tables and snapshots are read through the storage listing, at no query cost. Views and external tables need a query: it runs with a byte limit (At most per table in BigQuery, 1 GB by default), and one that would read more fails with that reason instead of being billed. |
| Databricks | A query per table on the SQL warehouse. The schedule never starts a stopped warehouse: a run due while it is stopped waits an hour. Profile this schema says it will start it. Metric views are skipped. |
| Snowflake, Trino / Starburst, PostgreSQL, SQL Server, Oracle, Teradata, Cloudera | A SELECT limited to the sample size (LIMIT, TOP or ROWNUM), with the table's full name. |
| Salesforce, Kafka | Not profiled: they have no tables Qry can sample. |
What is never shown
The most frequent values of a column are what makes a profile useful, and also what could repeat personal data. They are withheld — from the model and from the table page — when:
- the column carries an attribute-based access tag;
- its name can only mean personal data (e-mail, phone, ID or passport number, IBAN, card number, birth date, first, last or full name);
- or its values look like it (e-mail addresses, phone numbers, Spanish ID numbers, IBANs).
The page says why (Not shown: they look like personal data). Names that only contain such words keep their values: nombre_linea, tipo_tarjeta or direccion_almacen are codes people filter on, not personal data. Counts, missing values and ranges are always shown.
Common issues
A data source shows "No tables known yet". Coverage counts the tables in Qry's schema cache, filled by the nightly schema refresh or when someone opens the schema. Open it in the catalog, or wait for the refresh.
A table keeps failing. The reason is on its table page and in the schema's readiness. Typical: the service account cannot read it, or a view fails on its own data (an invalid date in a source column). Fix the cause, then Profile again.
A view on BigQuery says it would cost more than the limit. Raise At most per table in BigQuery in the schedule, or leave the view out.
The same schema name in two catalogs. Each profile keeps its catalog. Profiles written before Qry kept the catalog serve any catalog until the table is profiled again.
See also
- Readiness for AI — where profiling gaps are shown and acted on.
- Connecting databases — the data source has to exist first.
- Data profiling — what profiling gives people who ask questions.
- Monitoring and health — Celery worker health.